Overview
As far as speech-to-text is concerned, they offer Scribe v2 for batch transcription and Scribe v2 Realtime for low-latency streaming transcription. Languages supported by ElevenLabs reportedly numbers 90+, along with speaker diarization, word level timestamps, keyterm prompting, and dynamic audio tagging.
This provides a wide array of options for developers looking for speech-to-text, synthesized speech, voice cloning, dubbing, and voice-agent functionality all in one place. However, it isn’t going to be ideal for every speech-to-text use case. Companies will likely look elsewhere when they need:
- Lower cost transcription at scale
- Highest accuracy possible on noisy, real-world conversational audio
- Best-in-class handling of overlapping speakers, interruptions, accents, background noise, etc.
- Additional intelligence derived from the audio itself (not just the transcript)
- Signals such as emotion, accent, and deepfake detection without relying on multiple vendors
- Predictable pricing for processing massive amounts of audio
There are several ElevenLabs alternatives that balance transcription accuracy, latency, language coverage, audio intelligence, deployment options, and price. In this post, we’ll compare:
- Modulate Transcribe
- Deepgram
- AssemblyAI
- Speechmatics
- Google Cloud Speech-to-Text
- Amazon Transcribe
- OpenAI Whisper
What is ElevenLabs?
ElevenLabs is an AI audio platform that was founded as a synthetic voice/text-to-speech company. They now offer related products such as:
- Text-to-speech
- Speech-to-text
- Voice cloning
- Voice changing and voice isolation
- Dubbing
- Conversational AI and voice agents
- Music and sound effect generation
ElevenLabs speech-to-text capabilities are built around a product called Scribe. ElevenLabs advertises that Scribe v2 offers support for 90+ languages, speaker diarization, word-level timestamps, keyterm prompting and dynamic audio tagging (allows you to tag non-speech events such as laughter, music, etc.). Scribe v2 Realtime includes streaming transcription capabilities and promises approximately 150 ms latency. Finally, ElevenLabs has developed a Scribe v2 Medical model that’s trained specifically for medical audio.
Needs for speech recognition often co-exist with needs for synthetic or generated voice. ElevenLabs makes sense when building an application that has both components. For example, a voice agent needs to both hear (speech-to-text) and speak (text-to-speech). Another example is a media pipeline that might involve transcribing audio then dubbing it with synthetic voice.
ElevenLabs Pricing
The standalone Scribe v2 batch transcription costs $0.22 per audio hour through ElevenLabs’ pay-as-you-go API. Scribe v2 Realtime runs $0.39 per hour. Each of these Scribe add-ons is priced on top of the base API rate. Rates published as of this writing:
| Product | Price |
|---|---|
| Scribe v2 / Scribe v2 Medical (batch STT) | $0.22/hour |
| Scribe v2 Realtime (streaming STT) | $0.39/hour |
| Entity detection add-on | +$0.07/hour |
| Keyterm prompting add-on | +$0.05/hour |
| Text-to-Speech v4 | $0.08 per 1,000 characters (promotional $0.022 through Oct 12) |
| Text-to-Speech v4 Turbo | $0.04 per 1,000 characters (promotional $0.011 through Oct 12) |
| Text-to-Speech v3 / v2 Multilingual | $0.08 per 1,000 characters |
| Text-to-Speech Flash / Turbo / v3 Conversational | $0.04 per 1,000 characters |
| Speech Engine (agents) | $0.08/minute |
| Voice Changer / Voice Isolator | $0.12/minute |
| Dubbing v1 | $0.33/minute with watermark, $0.50/minute without |
| Dubbing v2 | $2.20/minute |
| Music generation | $0.15/minute |
Batch transcription costs $0.34 per hour when running with both add-ons enabled. Subscription plans (Starter through Business) bundle included hours and credits together, while annual Business plans also promise Realtime pricing of $0.28 per hour or less.
Why Consider an ElevenLabs Alternative?
Scribe is a powerful model. But ElevenLabs was founded first and foremost as a voice-generation company. If the core workload of your team is understanding voice rather than generating it, you’ll likely look to providers who specialize in listening for four reasons:
Lower cost of transcription. Pricing for Scribe starts at $0.22 per batch hour and $0.39 per streaming hour, before add-ons. That adds up for contact centers, platforms and anyone transcribing thousands of hours per month.
Higher accuracy on real-world conversations. Podcasts and narration are great. But phone calls, voice chat and support lines are full of crosstalk, interruptions, accents and background noise. Performance on that kind of audio isn’t consistent across vendors.
Additional insights from the original audio. While a transcript tells you what was said, it doesn’t tell you how it was said. Tone, emotion and evidence of synthetic or manipulated voices are all found in the audio waveform.
Providers that specialize in listening to vs. generating voice. If your needs don’t include TTS, voice cloning or dubbing, you may find a company that specializes in understanding voice better suits your needs.
7 Top ElevenLabs Alternatives
Modulate Transcribe
Modulate provides audio- native voice intelligence technology designed around insights into real-world voice conversations. The Modulate product that most closely aligns with ElevenLabs Scribe for an apples-to-apples comparison is Modulate Transcribe.
Modulate Transcribe is Modulate’s speech- to-text model trained specifically for transcribing conversational audio such as support calls, meetings and social voice chat. Trained on over 500 million hours of conversations, Transcribe is built to perform reliably even when speakers interrupt themselves, talk over one another, or switch between differing audio qualities. Modulate Transcribe can:
- Perform batch transcription via REST
- Provide sub-second, real- time streaming transcription via WebSocket
- Transcribe 70+ languages, including support for dialects
- Identify speaker diarization at no additional cost
- Return timestamps
- Accept keyterm prompts (optional add-on, +$0.02/hour)
In addition to Transcribe, Modulate has a variety of additional models that can be appended to Transcribe or invoked individually, which are billed separately:
- Emotion detection (over 20 emotions, time-aligned for each speaker)
- Accent identification (providing per-speaker accent labels)
- PII/PHI tagging, or comprehensive PII/PHI redaction of both the transcript and the audio file itself, either in batch or in real-time
- Deepfake detection to identify AI-generated and cloned voices
For enterprises that require conversation-level insights rather than individual signals, Modulate offers its flagship Velma platform. Velma is Modulate’s Ensemble Listening Model (ELM), which orchestrates Transcribe with additional specialized models to identify fraud, intent, sentiment, stress, speaker roles and behaviors, complete with time-stamped evidence connected to every second of every call. Velma itself is a separate, higher-tier product. It’s not what we’re comparing to Scribe on price. However, it does allow teams that start with Transcribe to scale to more advanced voice intelligence on the same platform, without needing multiple vendors.
Modulate Transcribe Pricing
Modulate’s published pay-as-you-go pricing, per hour of audio:
| Model | Batch | Streaming |
|---|---|---|
| Transcribe (Multilingual), diarization included | $0.03 | $0.06 |
| Transcribe (English Fast), diarization included | $0.025 | $0.05 |
| Emotion detection add-on | +$0.02 | Not available |
| Accent identification add-on | +$0.01 | Not available |
| PII/PHI tagging add-on | +$0.02 | +$0.02 |
| PII/PHI Redaction (audio + transcript) | $0.05 | $0.08 |
| Deepfake Detection | $0.25 | $0.25 |
| Velma (up to 10 / 25 behaviors) | $0.75 / $1.25 | $0.75 / $1.25 |
Speaker diarization is included in Modulate’s base Transcribe price. Everything else listed here is either an opt-in add-on or a separate model. You only pay for the signals you need.
Where Modulate Stands Out from ElevenLabs
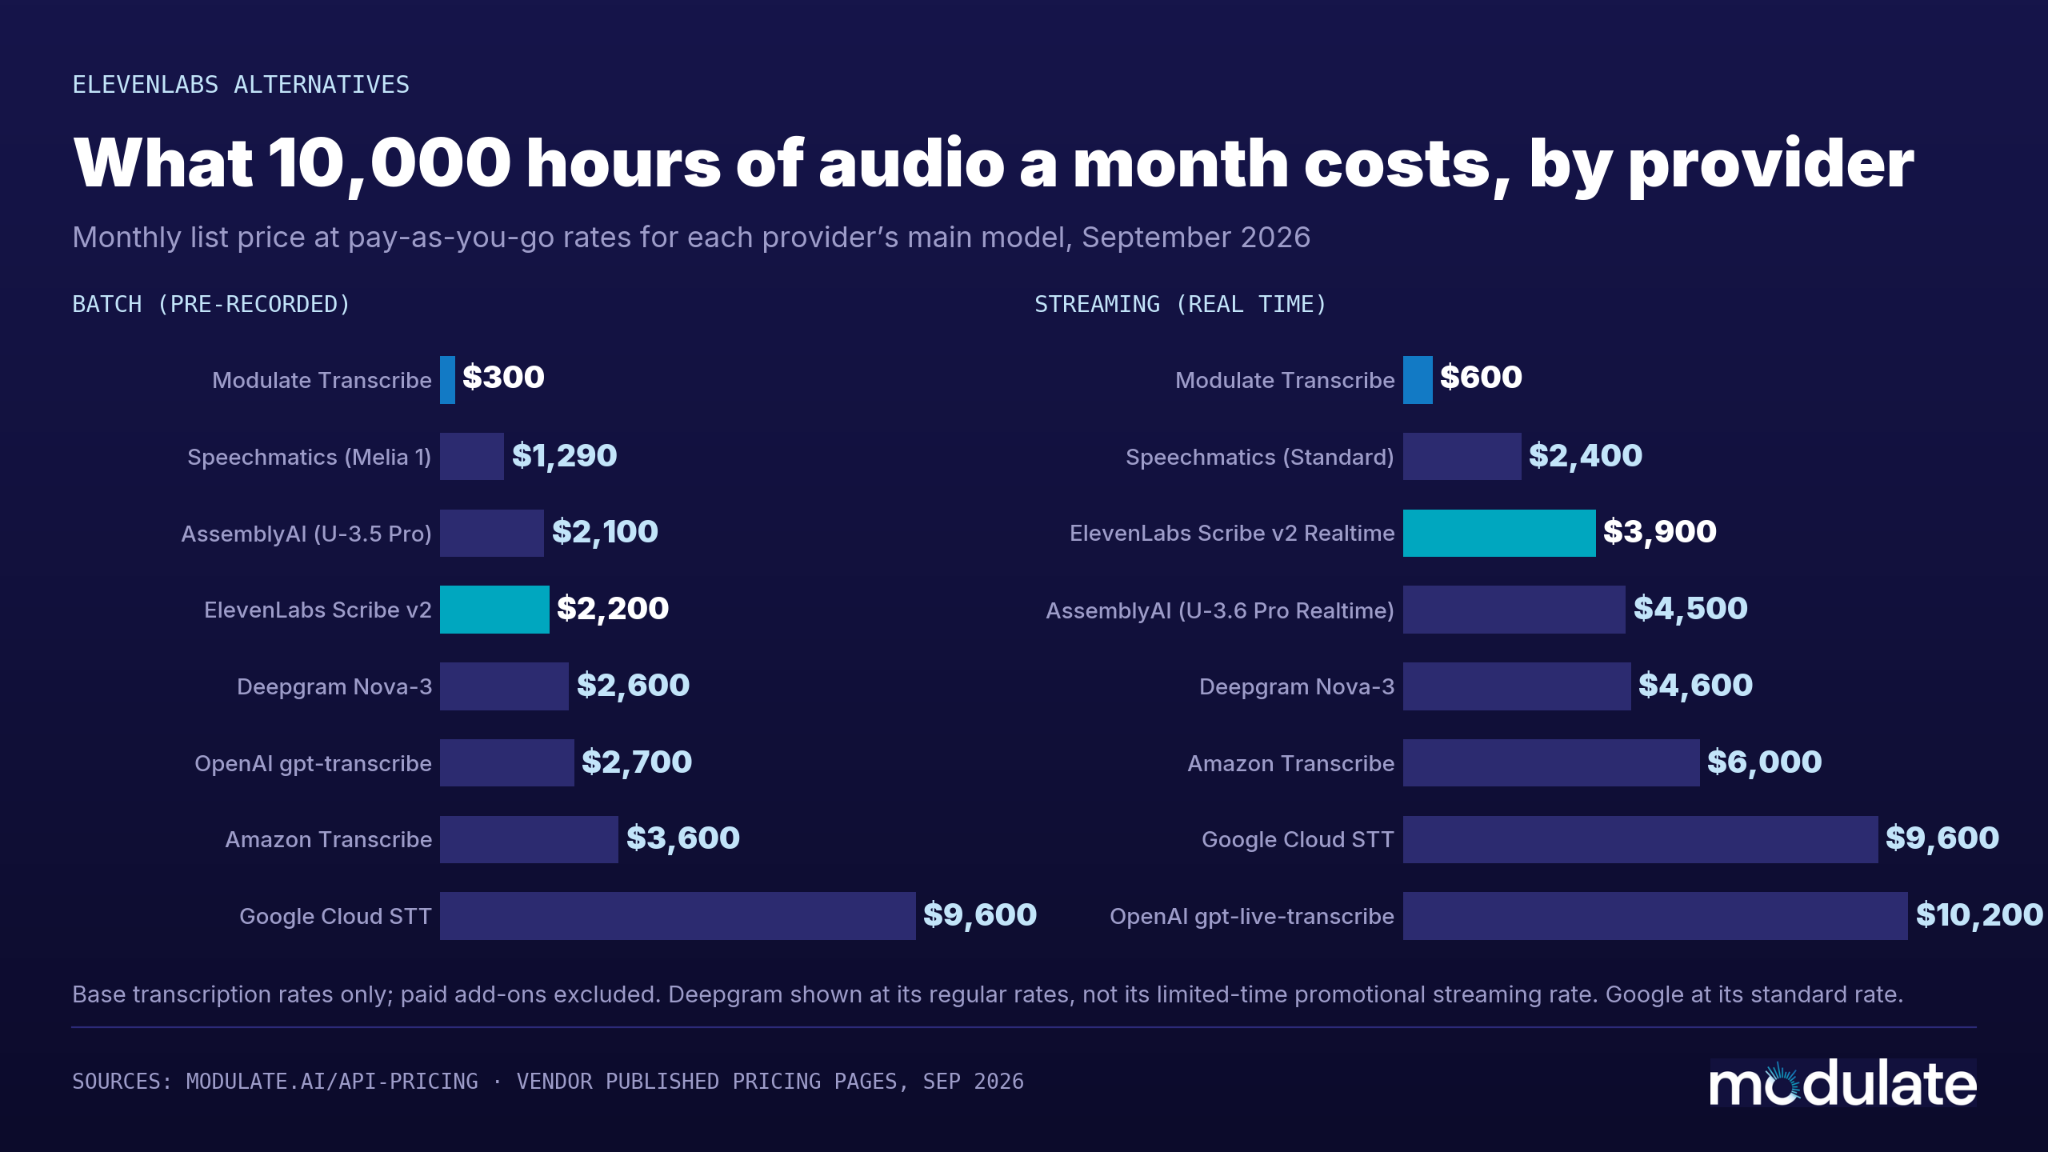
Cost. With multilingual support included, Transcribe charges $0.03/hour batch rate which is less than Scribe v2’s $0.22 rate. Transcribe charges $0.06/hour for streaming, which is less than Scribe v2 Realtime’s $0.39 rate. At 10k hours of audio per month, that translates to $300 vs. $2,200 per month for batch or $600 vs. $3,900 per month for streaming. With keyterm prompting enabled on both, batch transcription costs $0.05/hour on Modulate versus $0.27/hour on ElevenLabs.
Conversational accuracy. Specializing in conversational audio, Modulate Transcribe is trained on over 500 million hours of conversation and tuned for overlapping speakers, interruptions, slang, and other nuances you'll find in natural conversation. Its multilingual model ranks #3 on Hugging Face's Open ASR Leaderboard (as of September 2026), with the second-lowest word error rate of any model on AMI, a benchmark of noisy, real-life multi-speaker meetings.
Audio intelligence. ElevenLabs Scribe provides you with a transcript complete with tags and entities. Modulate’s broader Velma platform can also tell you how something was said, as well as whether the voice is real, synthetic or manipulated. It does this with proprietary models that analyze the audio signal itself, rather than text-based AI that tries to infer these characteristics.
Different platform focus. ElevenLabs is built around generating voice. Modulate has been built from the ground up to understand it.
Best for:
- Contact centers and QA workflows
- Voice AI applications and agents
- Gaming and social apps and platforms
- Trust and safety teams
- Fraud / deepfake detection
- High-volume conversational transcription
- Apps that process noisy or overlapping speech
- Organizations for whom transcription economics are critical
- Organizations that want to extract more intelligence from voice without having to stitch together multiple APIs
When building voice applications where generated voice, cloning, dubbing and TTS are core features, ElevenLabs is a solid choice. Modulate is the better alternative when those factors aren’t as important, and your priority is cost-efficient transcription of real-world conversations, with the option to add deeper intelligence from the original audio.
Deepgram
Deepgram provides a speech-to-text and voice AI platform optimized for production transcription workloads and low-latency streaming. Nova-3 is Deepgram’s general purpose STT engine. Flux is Deepgram’s conversational voice-agent model with built-in turn detection. Deepgram also provides text-to-speech (Aura) as well as a Voice Agent API.
Key capabilities include:
- Batch and live transcription
- Over 50 languages supported by Nova-3, new languages released monthly
- Speaker diarization
- Keyterm prompting
- Noise robustness
- Industry and custom-trained models
- Self-hosted options for enterprise customers
- Voice-agent tooling
- Developer APIs and SDKs
Deepgram vs. ElevenLabs
Both Deepgram and ElevenLabs support production STT and broader voice AI applications. Deepgram leads in real-time transcription and voice-agent infrastructure. ElevenLabs has a wider generated audio suite with products like voice cloning, dubbing, music and sound effects.
If you only need STT infrastructure and real-time voice applications, Deepgram will probably serve you better. But if synthetic voice is as important (or more important) than transcription, ElevenLabs might be the better choice.
Deepgram’s pay-as-you-go pricing for Nova-3 starts at $0.29/hour for monolingual streaming, while ElevenLabs Scribe v2 Realtime is $0.39/hour. The $0.29/hour rate is a temporary promotional price as of this writing (standard price is around $0.46/hour), and diarization is an additional $0.12/hour for streaming. Pricing for pre-recorded Nova-3 audio is $0.26/hour for monolingual and $0.31/hour for multilingual.
AssemblyAI
AssemblyAI is a developer-first speech AI platform offering APIs for pre-recorded (async), synchronous, and streaming speech-to-text. AssemblyAI also has capabilities beyond transcription, approaching speech understanding at scale.
Their flagship pre-recorded model, Universal-3.5 Pro, supports 18 languages at the highest accuracy. It reverts to Universal-2 for coverage of 99 languages. For streaming, Universal-3.6 Pro Realtime supports 32 languages, while the lower-cost Universal-Streaming model ($0.15/hour) covers English only, with a multilingual version for five additional European languages.
Key capabilities include:
- Batch, synchronous, and streaming transcription
- Speaker diarization
- Keyterm spotting and natural-language prompts
- Code switching and language detection
- PII Redaction
- Sentiment analysis, entity detection, summarization
- Medical Mode for clinical dictation audio
- Voice Agent API (STT, LLM and TTS bundled)
- Large Language Model (LLM)-powered speech-understanding features
AssemblyAI vs. ElevenLabs
AssemblyAI was founded on speech-to-text and speech-understanding capabilities. ElevenLabs was founded on text-to-speech and generated voice capabilities. AssemblyAI may be the better choice when building developer applications that need transcription coupled with downstream, transcript-based analysis. ElevenLabs holds the stronger portfolio for applications where TTS, voice cloning, dubbing, and generated audio are central requirements.
Rates are competitive for batch processing: Rates are competitive for batch processing: Universal-3.5 Pro is $0.21/hour compared to $0.22/hour for Scribe v2, but AssemblyAI is more expensive for streaming: Universal-3.6 Pro Realtime is $0.45/hour vs. $0.39/hour for Scribe v2 Realtime. Both charge for add-ons: ElevenLabs adds $0.07/hour for entity detection and $0.05/hour for keyterm prompting, while AssemblyAI charges extra for speaker diarization ($0.02/hour pre-recorded, $0.12/hour streaming), PII text redaction ($0.08/hour pre-recorded), and keyterm prompting ($0.05/hour on Universal-3.5 Pro). At the end of the day, it comes down to whether your use case is more speech-understanding or speech-generating focused.
Speechmatics
Speechmatics is a mature speech recognition provider with significant multilingual capability. The service supports batch and real-time transcription in 55+ languages and is available for cloud, on-premises and on-device deployment to meet stringent enterprise data residency or privacy needs. Speechmatics recently introduced low-latency text-to-speech (English only).
Key capabilities include:
- Batch transcription
- Real-time transcription
- 55+ languages supported, including the option to generate multilingual transcripts from a single file
- Speaker diarization
- Automatic language identification
- Custom dictionaries and vocabulary
- Medical model for use with healthcare data
- Multi-region cloud deployment options
- Flexible enterprise deployment options (on-prem/on-device)
Speechmatics vs. ElevenLabs
Speechmatics has a narrower focus on speech recognition and enterprise-grade transcription, while ElevenLabs is offering a more comprehensive voice-generation platform. Speechmatics is a great alternative for multilingual transcription needs and for companies that place a higher value on STT than generated voice, especially if self-hosted deployment is a concern.
Speechmatics Pro pricing starts at $0.129/hour for its multilingual batch model, while ElevenLabs Scribe v2 starts at $0.22/hour. For real-time transcription, Speechmatics' Standard tier is $0.24/hour, well below Scribe v2 Realtime's $0.39/hour, while its highest-accuracy Enhanced tier is $0.43/hour, slightly higher. A 20% discount applies automatically to usage over 500 hours per month for each type of transcription.
Google Cloud Speech-to-Text
Google Cloud Speech-to-Text is Google Cloud's speech recognition service. Their newest ASR model, Chirp 3 offers a multilingual model that supports 85+ languages and language locales. Chirp 3 includes support for speaker diarization and automatic language detection. Google Cloud Speech-to-Text makes sense if your organization is already heavily invested with Google's cloud infrastructure and AI technologies.
Key capabilities include:
- Batch, sync, and streaming recognition
- Wide variety of language support
- Automatic punctuation and capitalization
- Speaker diarization (available for batch only on Chirp 3, and for a subset of languages)
- Speech adaptation to add custom terms and proper nouns
- Integrates with Google Cloud Services
Google Cloud Speech-to-Text vs. ElevenLabs
Google has a larger cloud footprint and AI ecosystem. ElevenLabs is focused on voice technologies specifically spanning speech recognition and voice generation. Google Cloud Speech-to-Text will likely be preferable if transcription is just one need within an existing Google Cloud ecosystem. ElevenLabs will likely be preferable if developers want STT tightly integrated with TTS, cloning/dubbing functionality, or customized voice agents.
Google’s pricing page is pretty bare-bones, but their standard pricing for V2 is $0.016/min (roughly $0.96/hour) for the first 500,000 minutes consumed per month, with the price decreasing as you consume more minutes. The dynamic batch pricing tier, which reduces the price by increasing latency, is $0.003/min (roughly $0.18/hour).
Amazon Transcribe
Amazon Transcribe is AWS's managed automatic speech recognition service. Seamlessly connected to AWS storage, analytics, contact-center (Amazon Connect), and AI services, Transcribe supports 100+ languages and dialects.
Key capabilities include:
- Batch and stream transcription
- Speaker and channel identification
- Custom vocabulary and language models
- PII identification/redaction
- Call Analytics (sentiment, categorization, issue detection, summarization)
- Toxicity detection
- Medical transcription (HIPAA-eligible)
- Multi-language support
Amazon Transcribe vs. ElevenLabs
AWS has a much larger infrastructure ecosystem, while ElevenLabs has a more focused AI audio ecosystem. If your organization is already operating other parts of your stack on AWS, Amazon Transcribe may help you simplify your architecture. ElevenLabs has much more capability when it comes to generated voice, cloning and audio creation.
Standard Amazon Transcribe pricing is $0.006/min (about $0.36/hour) for batch and $0.01/min (about $0.60/hour) for streaming in US East, with speaker diarization, custom vocabularies and language identification included. Add-ons such as PII redaction and custom language models cost extra, and Call Analytics and medical transcription are priced higher. That puts standard Transcribe above ElevenLabs Scribe v2 ($0.22/hour batch, $0.39/hour streaming) and well above low-cost specialists, so it’s usually the right choice when AWS integration matters more than the lowest per-hour rate.
OpenAI Whisper
OpenAI Whisper is best known as a general-purpose solution for multilingual speech recognition and open-source and self-hosted transcription. The Whisper models themselves are open-source software, available under the MIT license so teams can run them however they want on their own infrastructure. OpenAI also provides managed alternatives to the original Whisper API. In addition to gpt-4o-transcribe and gpt-4o-mini-transcribe, OpenAI has launched gpt-transcribe for file-based STT and gpt-live-transcribe for real-time streaming STT applications, both available as APIs in July 2026.
As a result, OpenAI tends to be the go-to provider for teams that either want an easy-to-use, managed transcription API or maximum flexibility with an open-source Whisper deployment that they can customize.
Key capabilities include:
- Multilingual speech recognition with support for 99+ languages
- Open-source Whisper models can be deployed on your own infrastructure
- Managed API options available for both file and streaming use cases
- Translation and word level timestamps with whisper-1
- Speaker diarization with gpt-4o-transcribe-diarize
- Large developer community
- Can be used for custom implementations
OpenAI Whisper vs. ElevenLabs
OpenAI Whisper allows organizations to self-host their speech recognition model, while ElevenLabs provides fully managed STT as part of a larger audio-generation suite. Hosting Whisper locally allows teams greater control over their infrastructure but requires the customer to handle scaling, optimization, diarization and upkeep. Whisper’s original models are also not ideal for real-time streaming use cases.
On OpenAI's managed API, whisper-1 costs $0.006/min ($0.36/hour), gpt-transcribe costs $0.0045/min (roughly $0.27/hour), and gpt-4o-mini-transcribe is $0.003/min ($0.18/hour). Using gpt-live-transcribe to stream audio is significantly more expensive at $0.017/min (around $1.02/hour). ElevenLabs is ideal for when an organization needs speech recognition and synthetic voice from one managed provider.
How to Choose the Best ElevenLabs Alternative
Test accuracy on your own audio. Published WERs are just a baseline. Benchmark audio is almost always cleaner than your call recordings or voice chat. Pull a representative sample of noisy real-world audio, run it through each shortlisted provider, and compare side-by-side.
Compare total transcription costs. Don’t be fooled by the headline rate. See what’s included (diarization, keyterm prompting, redaction), whether streaming is more expensive than batch, and whether a listed price is temporarily discounted. Here are today’s base rates:
| Provider (model) | Batch, per hour | Streaming, per hour |
|---|---|---|
| Modulate Transcribe (multilingual) | $0.03 | $0.06 |
| Speechmatics (Pro) | from $0.129 | $0.024 Standard / $0.43 Enhanced |
| AssemblyAI (Universal-3.5 Pro / Universal-3.6 Pro Realtime) | $0.21 | $0.45 (from $0.15 with Universal-Streaming) |
| ElevenLabs (Scribe v2) | $0.22 | $0.39 |
| Deepgram (Nova-3) | $0.26 mono / $0.31 multi | $0.29 mono / $0.35 multi (promotional) |
| OpenAI (gpt-transcribe / gpt-live-transcribe) | $0.27 | $1.02 |
| Amazon Transcribe (standard) | $0.36 | $0.60 |
| Google Cloud STT (V2 standard) | $0.96 ($0.18 dynamic batch) | $0.96 |
Consider your needs beyond a basic transcript. Need emotion, accent, PII/PHI redaction, or deepfake detection? Price out how each vendor provides them and whether you’ll need a second vendor to provide those features at all.
Understand your latency requirements. Live captioning and voice agents require sub-second streaming. But post-call analytics and archives can be handled with lower-cost batch processing.
Determine whether you need voice understanding or voice generation. If TTS, cloning and dubbing are core requirements for your products, having ElevenLabs’ platform as part of your stack is a real advantage. If your product is more focused on listening to and analyzing conversations, a listening-first platform will almost always be a better fit.
Factor in security and privacy needs. Look for certifications (like ISO 27001, HIPAA-eligible), data retention and training policies, redaction capabilities and on-prem or regional hosting options.
Why Modulate Is the Best ElevenLabs Alternative
ElevenLabs is designed to create voice. Modulate is designed to understand it. When your core product revolves around transcribing and processing real conversations, that core difference can have huge implications for cost, accuracy, and what you can do with the audio.
Significantly lower transcription costs. Modulate Transcribe is available for $0.03/hour in batch or $0.06/hour for streaming, including diarization, while ElevenLabs Scribe v2 costs $0.22 and $0.39.
Built for accuracy on messy, real-world conversations. Our Transcribe model is trained on 500M+ hours of conversational audio and fine-tuned for overlapping speakers, interruptions, accents and background noise.
Audio intelligence alongside transcription. Add emotion, accent, and PII/PHI tagging to Transcribe for just a few cents per hour each, so you can extract richer signals without needing a second vendor.
Multiple voice signals from one platform. Deepfake detection, audio redaction, language detection, and audio event detection are all available on our API, using the same credits and integrations.
Audio-native, real-time understanding. Most voice intelligence applications run an LLM over a completed transcript after the call has ended. Modulate’s models analyze audio directly, in real-time, understanding tone and emphasis that transcripts miss.
Purpose-built for understanding voice, not generating it. Every model on Modulate’s platform serves your listening use cases: understanding customers, players, callers, and virtual agents.
Real-time PII/PHI redaction of the actual audio. Modulate can output a redacted audio stream and redacted transcript in real time as the conversation takes place on 100+ entity types, helping teams completely eliminate the storage of sensitive data.
Specialized models working in tandem. To produce conversation-level insights, Velma teams up Transcribe with other purpose-built models, rather than relying on one all-purpose model. The output is time-stamped, auditable results.
Proven performance on public benchmarks. Modulate's Multilingual model ranks third on Hugging Face's Open ASR Leaderboard and posts the second-lowest error rate on AMI, one of the most challenging benchmarks for multi-speaker conversational audio.
Ready to see how Modulate performs on your audio? Get free API access and run your own comparison.